
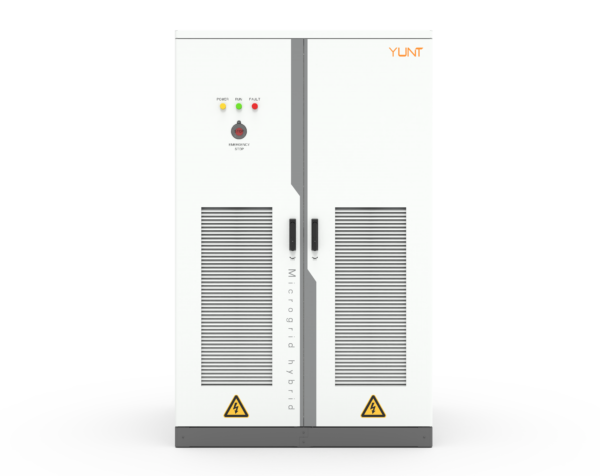
Why a framework matters
You want a toolkit that keeps inverters sane when systems demand both real and reactive power fast. Start with the basics: solid MPPT logic, stable inverter firmware, tight battery management. That’s why I map the work into repeatable modules — hardware, control loop, and test rig. For charge regulation, consider proven mppt charge controllers and a mature solar charge controller as part of the baseline; they’re not glamorous, but they keep voltage behavior predictable under pull-in and pull-out events.
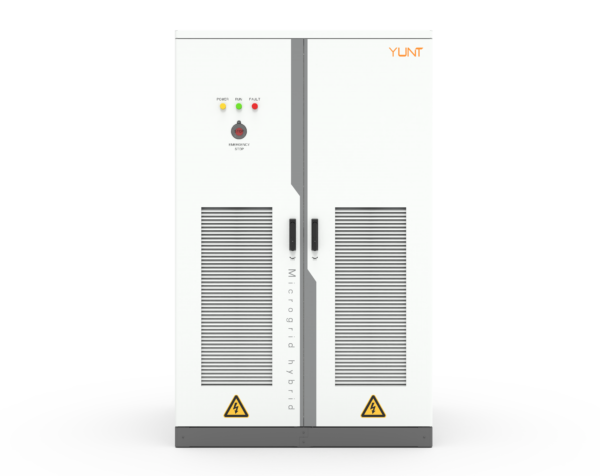
The R&D core blueprint — components and roles
Keep this tight: three lanes of responsibility. One, power electronics and inverter hardware — thermal paths, filter sizing, and switching topology. Two, control software — the four-quadrant active/reactive scheduler, anti-windup, and latency compensation. Three, system integration — microgrid sequencing, BMS handshake, and grid-support modes. Each lane has simple acceptance criteria: stability across state changes, bounded voltage sag under step loads, and deterministic latency under stress. Use bench tests and hardware-in-the-loop to validate.
Operational production teardown
Strip it down and look for where the cracks start. Common failure points: controller jitter, asynchronous sampling between converter legs, and too-ambitious reactive power ramps that the hardware can’t follow. Log the data at the converter input and output, then correlate control timestamps to physical response. When you do this, call out the obvious tags — {main_keyword} and {variation_keyword} — in your defect tickets so teams don’t miss them. Don’t skip the basics: check filter resonances and gate-drive health. If a module trips only under combined active/reactive commands, you’re likely chasing latency or loop mismatch, not a mythical board flaw.
Field lessons and the real-world anchor
Look at Texas in February 2021 — systems that weren’t designed for extreme transients showed how brittle some grid-interactive inverters can be when latency stacks up with thermal and frequency excursions. Teams that had modular R&D processes and staged control rollouts recovered faster. Thermal derating, conservative reactive schedules, and coordinated BMS commands made the difference in restoring stable voltages. That’s a real-world reminder: theory must meet field edge cases.
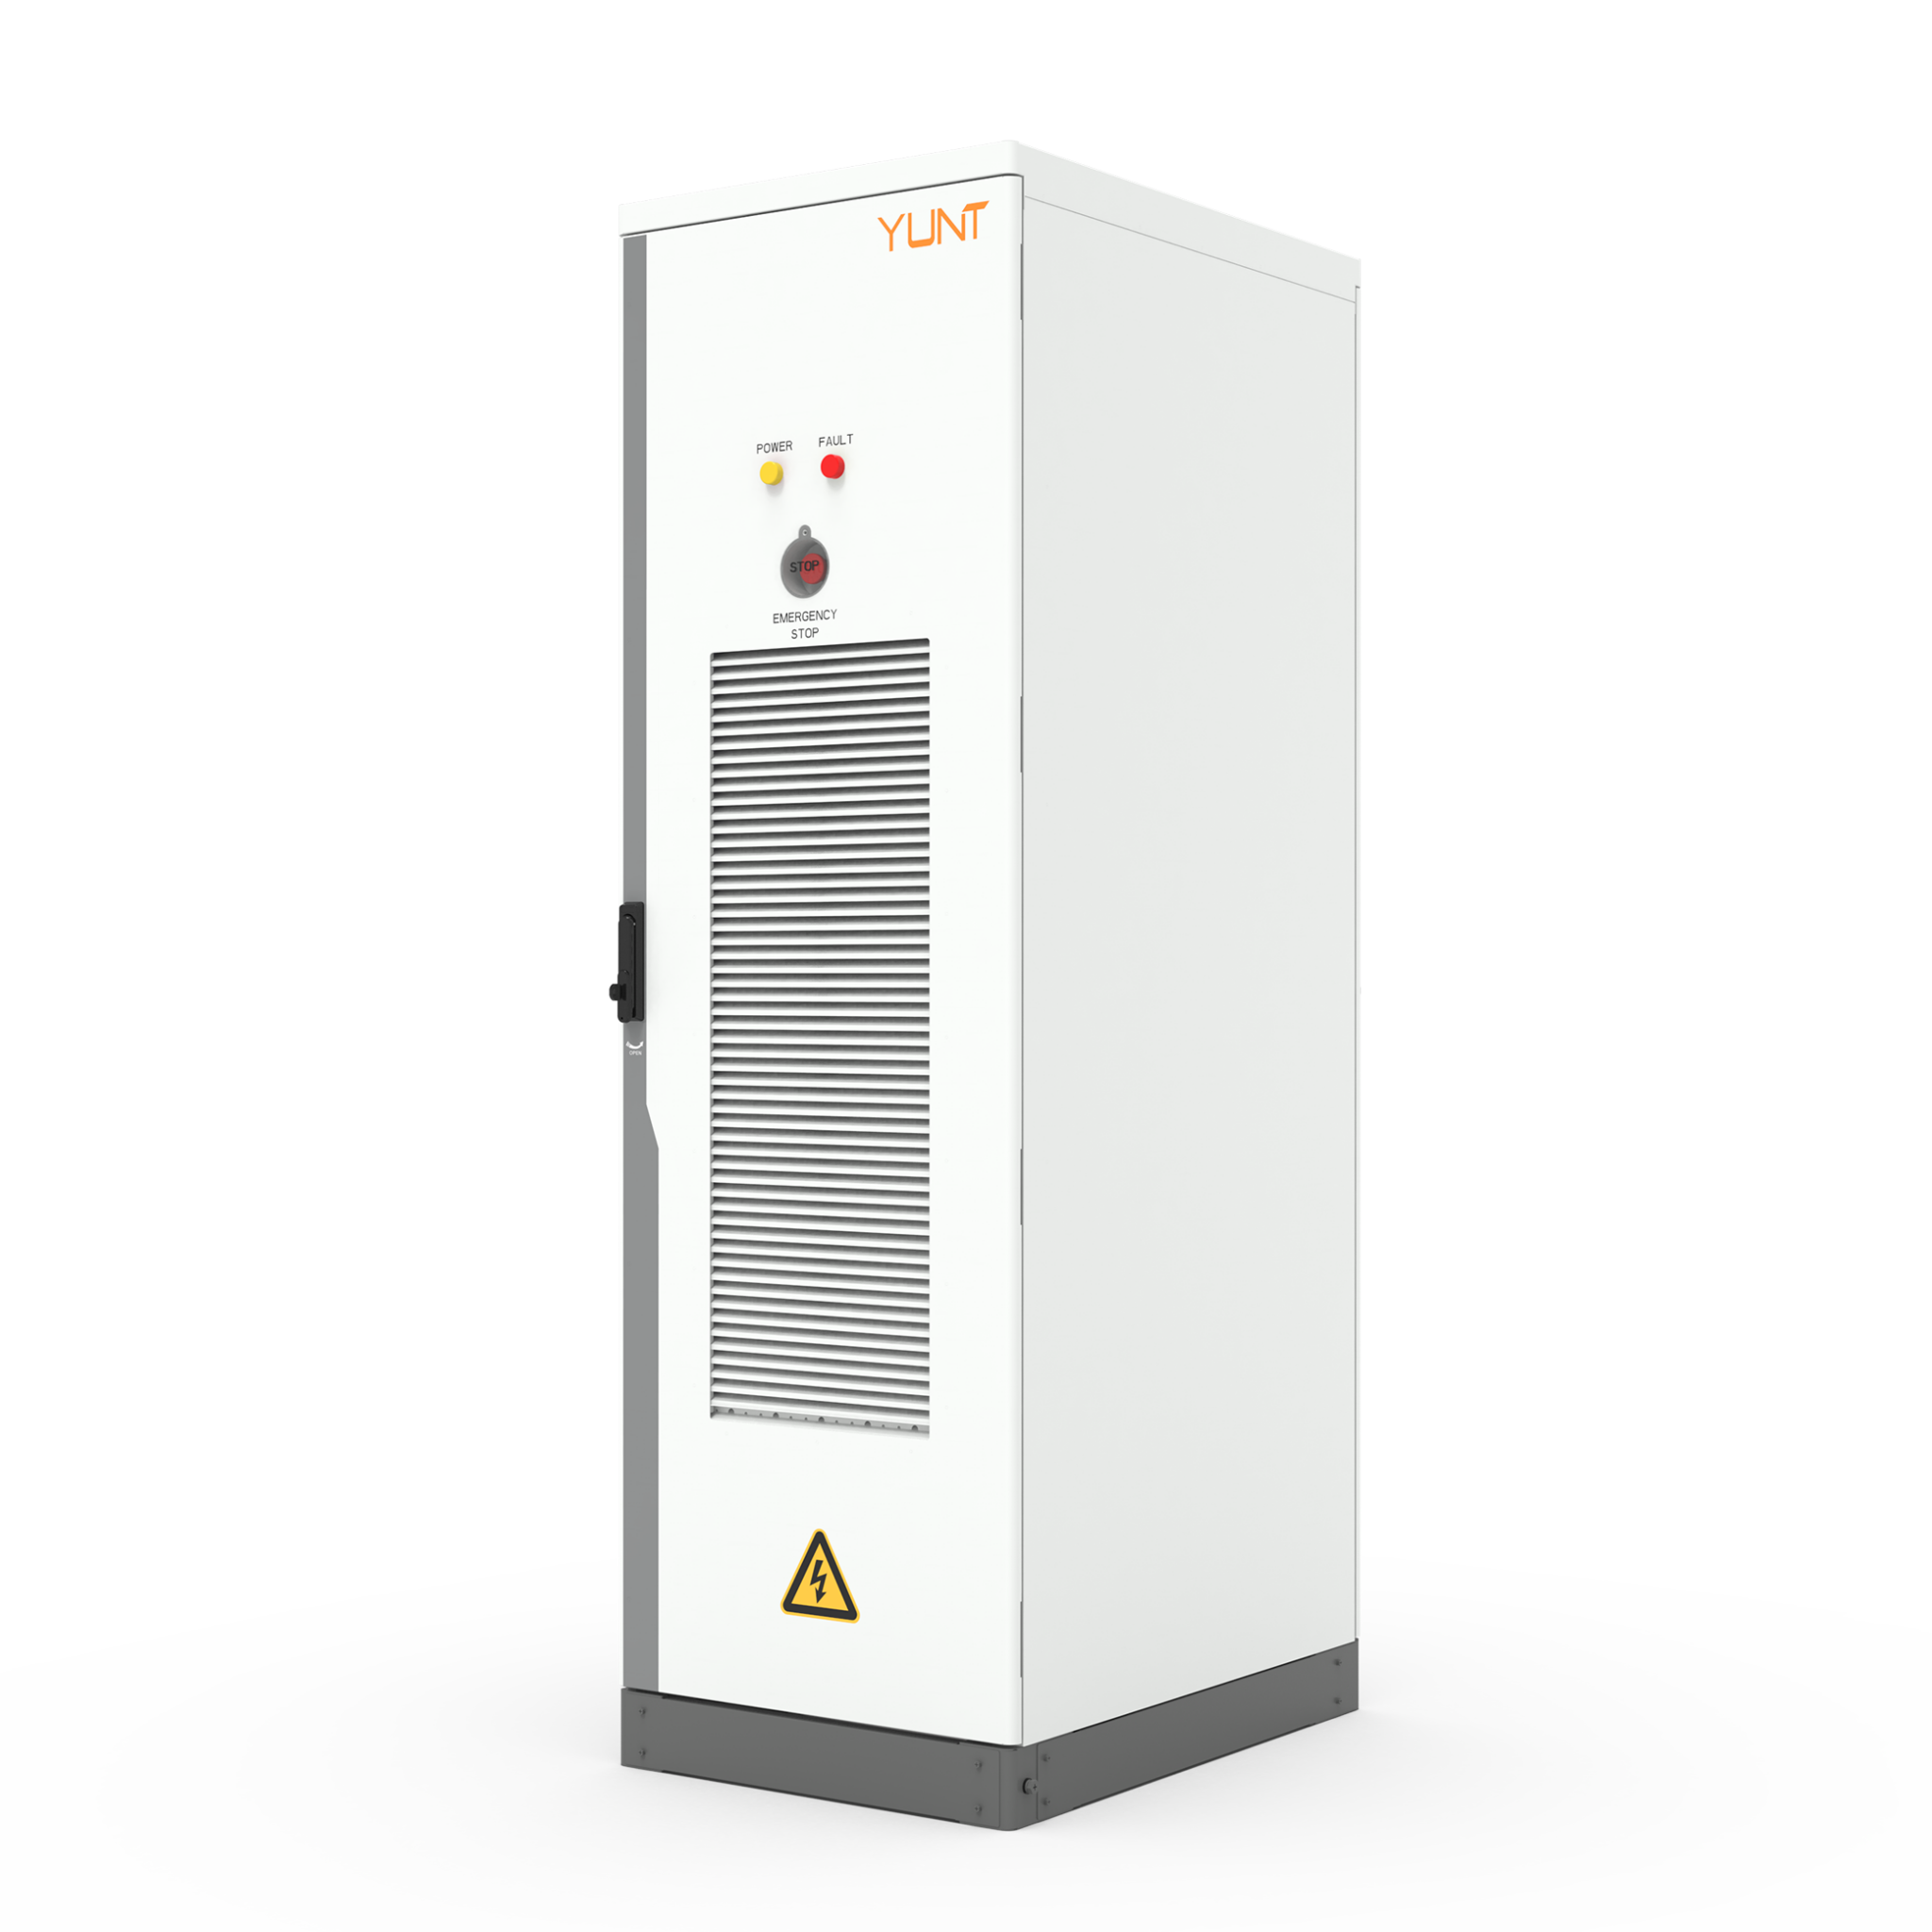
Common mistakes and fixes
Fixes that actually work: slow down the outer loop while you speed up inner current loops; add phase-lead compensation for the reactive path; and instrument latency across every communication hop. Avoid these traps: treating MPPT as an afterthought when inverter dynamics change under partial shading; assuming BMS will absorb any sudden SOC swing; and letting firmware updates slip without hardware regression tests. Quick wins usually come from clamp settings, filter retuning, and tighter watchdogs.
Practical rollout steps
Use a staged rollout: lab, HIL, pilot microgrid, then fleet. For each stage, measure three things — settling time after a four-quadrant command, peak voltage deviation during ramp, and control latency tail (95th percentile). Automate regression tests that inject reactive-power steps while logging thermal and frequency windows. Keep a short list of validated hardware: gate drivers, snubbers, and MPPT-capable converters. Track firmware versions and mark ones that pass latency budgets.
Advisory — three golden rules
1) Demand a latency budget up front: quantify allowable control lag in milliseconds and refuse to design without it. 2) Match control bandwidths: inner current loops must be at least 3× faster than outer reactive-power loops to avoid micro-fissures in response. 3) Validate on real grids: run pilot sites under scheduled islanding and extreme load steps before scaling — nothing substitutes live stress data.
Final word: this framework turns messy field surprises into predictable fixes — and that reliability is exactly what makes YUNT the practical choice for integrating MPPT, control, and system-level resilience. —